The AI Voice Is the Least Synthetic Part of a Viral Story
A red-suitcase story passed through synthetic narration, unrelated footage, automatic captions and multiple reposts. Labeling the voice alone misses the production system.
August 21, 2026 · 8 min read
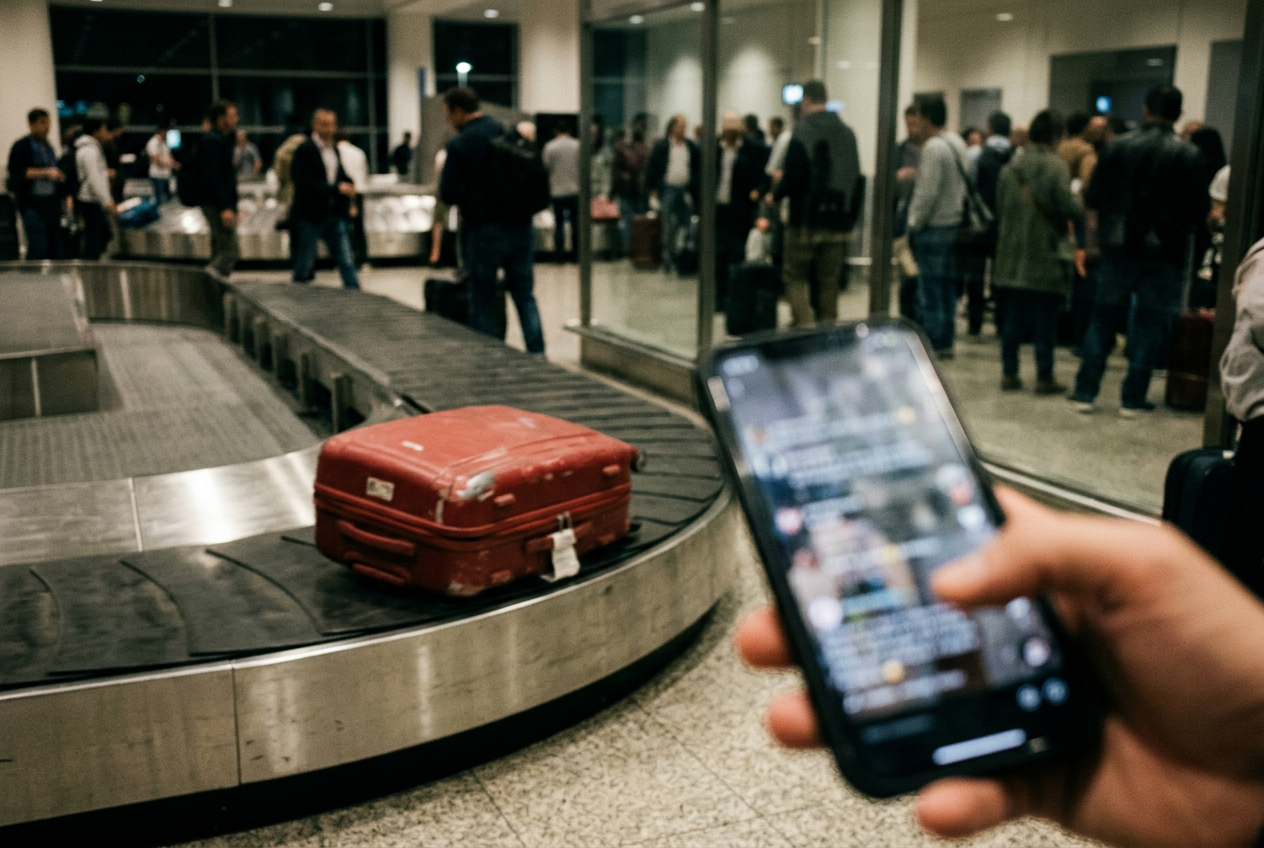
The specimen is a vertical video about a red hard-shell suitcase. The narrator describes an airline returning the wrong bag, then discovering clothes that supposedly belong to another traveler. The footage begins with a red suitcase circling an airport carousel. Later, unidentified hands open a black case on a bed.
By the time I saved the public post for evaluation, it carried two sets of captions. The lower set had been partly cropped away. A pale strip at one edge suggested that an earlier watermark had been covered or lost during resizing. The soundtrack combined an even, synthetic-sounding voice with low instrumental music, while the pictures changed often enough to keep the frame moving without establishing that they showed the event being described.
That last part matters. Nothing visible ties the red suitcase to the black one, the airport to the bedroom or either bag to the person whose story is being narrated. The video does not prove its account. It illustrates it.
Calling this an AI-voice video is technically plausible and analytically weak. The voice is one layer in a production chain that may include copied prose, machine rewriting, stock or stolen footage, automatic captioning, licensed platform music and a reposting account that originated none of them. Each layer has its own provenance, meaning the record of where material came from and what happened to it. The final post has almost none.
One post, several production systems
Start with the script. The suitcase story follows a familiar short-form structure: a first-person problem arrives immediately, a detail raises suspicion, the reveal lands near the end. That shape could come from a human writer, a Reddit post, a transcript copied from another video or text generated by a large language model, software trained to predict plausible sequences of words.
The finished prose cannot settle which route was used. Smooth grammar is not proof of automation, while awkward phrasing is no longer proof of a person. Detection tools that claim to identify AI writing infer likelihood from patterns in text; they do not recover a missing document history. A human can also prompt a model, revise two sentences and publish the result under an account that presents the story as personal experience.
The red suitcase adds emotional specificity without adding verification. It gives the viewer an object to track, and the opening footage supplies that object on cue. Yet the script and image need never have met before an editor searched a stock library or another platform for airport-baggage footage. A text-to-video system is unnecessary.
Ordinary search, screen recording and a template editor can produce the same effect faster.
The narration is easier to classify. Its pace stays unusually regular, breaths are absent and emphasis falls on a few odd syllables. Those are common signs of text-to-speech, software that converts written text into spoken audio, though compression and aggressive editing can complicate the judgment. Even a confident identification answers only how the words became sound.
It says nothing about whether the event occurred.
Captions create another authorship layer. Automatic speech recognition, which turns spoken audio back into text, appears to have generated the lower captions before someone added a second set in a different style. One caption layer follows the voice closely. The other condenses phrases and shifts line breaks to place the reveal on screen later.
Automation produced raw text; editorial timing shaped attention.
Music is easier to ignore because it sits low in the mix. It still does work. The track maintains tension under otherwise disconnected images and can come from a platform library, an editing app or an earlier post whose audio was copied with the video. Its presence may also affect distribution when a platform groups posts around reusable sounds.
A piece of licensed music can therefore outlive the license conditions attached to the upload that first used it.
The footage proves less than it feels like
The airport shot looks documentary because airports are real places and baggage carousels perform a recognizable function. That is the entire evidentiary contribution. The clip contains no continuous action connecting the carousel to the later bedroom, and the change from the red hard-shell suitcase to the black fabric case breaks the visual claim rather than supporting it.
Short-form editing makes that break easy to miss. The voice supplies continuity while the pictures supply novelty, so viewers process the footage as confirmation even when each shot is merely relevant to a noun in the sentence. Bag appears with bag. Airline appears with terminal.
Clothes appear with clothes. Semantic agreement replaces evidence.
This is where the real-versus-fake distinction starts to fail. The carousel footage may be authentic footage of a real suitcase. The bedroom footage may also be authentic. Neither must depict the narrated incident.
A video can contain no generated images and still make a synthetic factual claim by combining unrelated material under a single voice.
The useful audit asks what each layer is doing. The script makes the allegation. The pictures make it feel witnessed. Captions keep it legible without sound.
Music manages tone. The account and platform place the package in circulation. Accountability disappears when those functions are treated as one object called content.
Reposting removes the production history
The sampled post had undergone at least one earlier export. The evidence was mechanical: clipped lower captions, inconsistent margins and a covered edge where another interface element had likely been present. None identifies the first uploader. They show that the version in front of me was downstream.
Reposting can mean using a platform’s built-in share tool, downloading a file or recording the screen while it plays. Each method preserves different information. A native share may retain an account link. A downloaded file can lose the surrounding caption and comments.
A screen recording turns every visible element, including captions and watermarks, into pixels inside a new file.
That conversion matters for provenance systems. Content Credentials, based on the C2PA technical standard, can attach signed information about a file’s origin and edits. The record can help when compatible tools preserve it. It cannot force a screen recording to carry the same history, and it does not establish that a narrated claim is true.
It documents handling, not reality.
The red suitcase survived every transformation because it was useful. The account name did not. The source of the script did not. Any permission attached to the footage did not.
A durable object and disposable attribution are good conditions for reposting at volume.
Platforms contribute to this loss even when their policies require disclosure of realistic synthetic media. A label attached to one upload does not necessarily travel with a downloaded copy, while a generic AI marker rarely says whether it applies to the voice, image, script or all of them. The viewer receives a warning without an audit trail.
Ranking rewards the package, not the provenance
Recommendation systems rank posts using many signals, including viewing behavior, interactions and predicted relevance. They do not need to determine whether the suitcase story belongs to the uploader before testing whether viewers keep watching. The cliffhanger structure helps. So do large captions and visual changes timed to prevent a static frame.
Low-cost automation changes the economics because it reduces the labor required for each trial. An operator can adapt a story, generate narration, retrieve generic footage and export variants without filming a person or location. Most posts can fail. The production method remains attractive if a small share draws enough attention to feed advertising, creator payouts where available, affiliate offers or traffic toward another account.
The harms are distributed differently. A person whose story was copied may lose control of it. A camera operator may see footage detached from its license or context. A viewer may mistake illustration for evidence.
The reposting account gets the cleanest role: publish, measure, repeat.
Platforms could make that role less clean by requiring layer-specific disclosures and preserving them across native reposts. A useful notice would separate synthetic narration from generated imagery, identify externally sourced footage and point to the upload from which the current post was derived. Monetization checks could demand stronger provenance when an account repeatedly publishes first-person stories with no visible connection to their subjects.
That would add friction. Good. The current system places nearly all verification work on the viewer, who has seconds to inspect a red suitcase while the next caption is already arriving.
Questions people ask
How can you tell whether a viral story uses an AI voice?
Listen for regular pacing, missing breaths, repeated intonation and strange emphasis, but treat those as clues rather than proof. Compression, voice processing and tight editing can create similar effects. The stronger evidence comes from a platform disclosure or a preserved production record identifying the text-to-speech tool.
Does real footage mean the narrated story is real?
No. Real footage can be unrelated to the event described. In the sampled video, the red suitcase on the carousel and the black case opened later were connected only by narration and editing, which created continuity without documenting a continuous event.
Why do accounts make these videos at such high volume?
Templates and automation reduce the cost of testing many stories against a recommendation system. Revenue may come from platform programs, advertising, affiliate links or traffic sent elsewhere, but the immediate objective is usually repeatable attention rather than a durable relationship with one reported story.
What should platforms label in an AI-narrated video?
Labels should identify the affected layer: script, narration, image, footage or captions. They should also preserve repost lineage and distinguish generated media from authentic footage used out of context. A single AI badge leaves the central accountability problem untouched.
One update a day
Today's story, in your inbox
One story each morning — no hype, no filler, no algorithm deciding for you.