TikTok Search Writes the Celebrity Rumor for You
Autocomplete does more than reflect curiosity. It ranks a rumor, puts it in neutral interface text, and hands the next user a ready-made suspicion.
August 14, 2026 · 8 min read
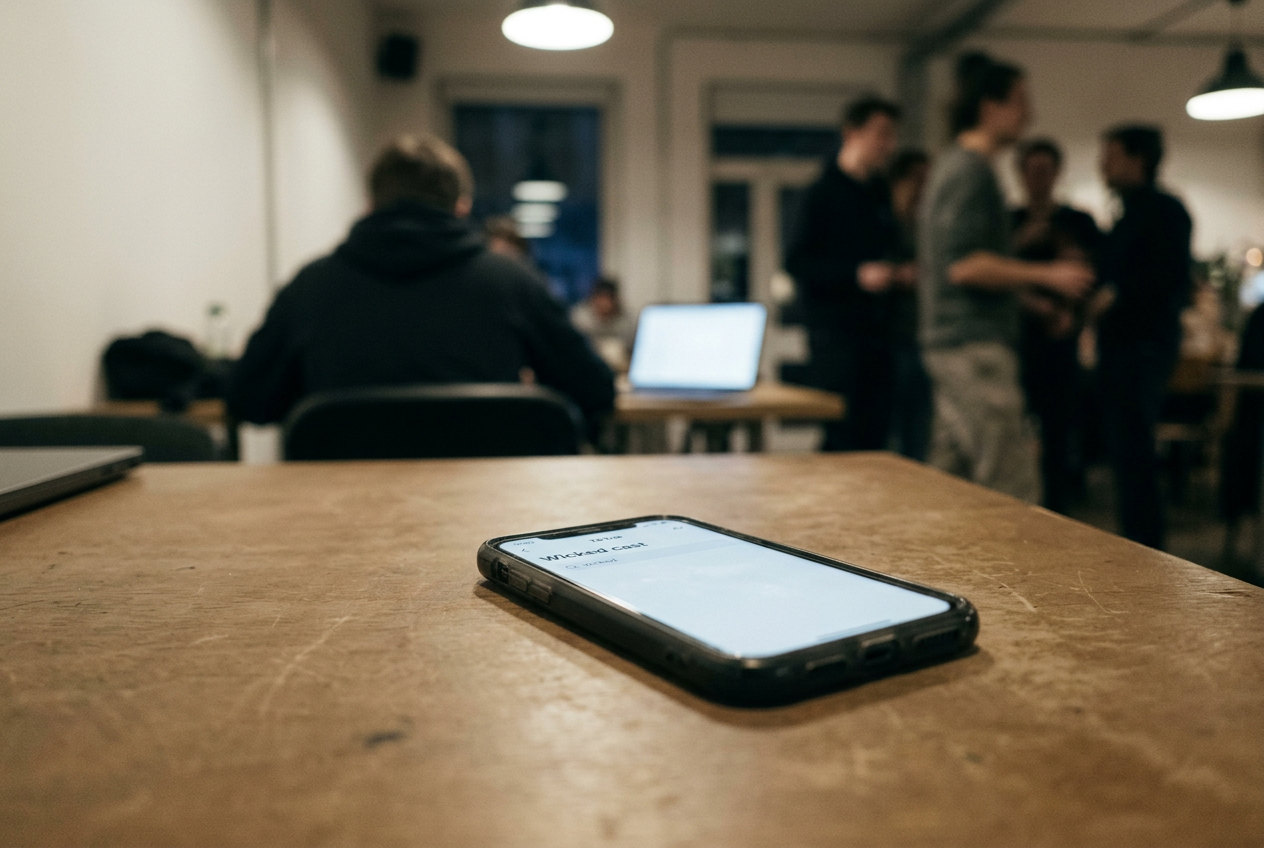
The object at the center of this story is small enough to miss: the gray completion that appears beneath TikTok’s search bar after someone types “Wicked cast.” The user has supplied two words. TikTok supplies the suspicion.
That second part matters. A person may arrive looking for a cast interview, a performance clip, Cynthia Erivo’s costumes, Ariana Grande’s vocals, or the name of an actor they recognize. Autocomplete narrows those possible intentions into a ranked set of phrases, and any phrase about a feud, relationship, body, illness, firing, or private life arrives with the composure of a menu option. No frantic caption.
No account with a Minion avatar. Just interface text.
Autocomplete is a prediction system that offers likely query endings before a user finishes typing. TikTok does not publish a sufficiently detailed account of how each entertainment suggestion earns its position, so an outside evaluation cannot honestly assign exact weights to search volume, recent activity, location, language, video supply, or engagement. The visible result still tells us something concrete: TikTok chose to place one phrase in front of the next searcher.
That choice turns rumor into a question everyone appears to be asking.
The clean account is not a clean room
A useful evaluation begins with a new account, no follows, no likes, no watch history, and no previous searches. Then the same operator enters fixed stems around several verifiable entertainment stories, recording the screen after every added letter. “Wicked cast” works as the anchor because the underlying fact is plain: there is a film, it has a credited cast, and users have many legitimate reasons to search for it.
Control queries can sit beside it. A film title followed by “cast,” an album title followed by “release,” and a series title followed by “season” create boring factual baselines. The operator should also repeat each query while logged out where the app permits it, note the device language and broad region, avoid opening results between runs, and return at different times. Autocomplete moves.
A screenshot without those conditions is a souvenir, not a finding.
The clean account has limits. TikTok still knows the device’s language, network location, operating system, and whatever contextual signals it can lawfully collect before the account develops a viewing history. Trending searches can dominate personal history anyway. “Clean” means reduced personalization, not a sterile view of the platform.
That limitation is useful. If a loaded completion appears on a new account, the user cannot have trained TikTok to show it through weeks of fandom videos. The suggestion may reflect broader search behavior or some other ranking signal, but TikTok has chosen to distribute it beyond the people who first entered the phrase.
There is also a reporting line this article will not cross. Without live access to the app during publication, I will not print supposed current completions after “Wicked cast,” or after any celebrity’s name, and dress guesses up as hands-on findings. Those strings must be captured, timestamped to the month, checked across repeated runs, and reviewed again immediately before publication. Autocomplete is too volatile, and allegations about real people are too consequential, for reconstructed screenshots or remembered wording.
The mechanism does not depend on a particular rumor staying in the box. The gray completion is the concrete evidence. Record what TikTok writes after “Wicked cast,” compare it with the factual controls, and the platform’s editorial act becomes visible.
Reflection is still distribution
Platforms like to describe autocomplete as a reflection of user interest. That account is incomplete in the same way a supermarket would be incomplete if it said the products at eye level merely reflected what shoppers wanted. Demand matters. Placement changes demand.
Suppose many users independently search a loaded phrase about a performer. TikTok detects enough activity to rank that phrase as a completion. The next group types only the performer’s name, sees the phrase, and taps it. Those taps create more searches for the same wording, while videos optimized around that wording receive a fresh audience.
Creators notice the traffic and publish more clips that repeat the phrase in captions, on-screen text, speech, or comments. The rumor now has search inventory.
This is a feedback loop, meaning an output returns as an input and strengthens the next round. TikTok does not need to invent the allegation. It needs only to format existing curiosity as a useful prediction, then count the behavior that prediction helped produce.
The distinction between user speech and interface speech gets blurred here. A creator’s caption belongs to that creator and comes attached to an account, however flimsy its sourcing. An autocomplete phrase belongs to the product surface. It appears before the results, without a speaker, citation, confidence score, or visible explanation of why it ranked.
TikTok has stripped away the source while preserving the claim-shaped wording.
A question can carry an accusation without asserting it directly. Search language is especially good at this. “Did,” “why,” “fired,” “dating,” and “sick” can convert a speculative premise into a neat request for information. The grammar asks the person being discussed to disprove the box.
Return to “Wicked cast.” A user who intended to find credits can be taught that the more urgent subject is private conduct between cast members. Even if the user never taps, the association has been delivered. Impression-level exposure matters because autocomplete can seed a proposition without sending anyone to a video where the proposition might be challenged.
Search content is built to close the loop
TikTok search results do not resemble a neutral library catalog. They are videos competing for attention, and many are made after creators notice what people are searching. A completion therefore does more than route demand toward existing material. It can provide a production brief.
The creator incentive is straightforward. A video that matches an active query may gain search traffic, and traffic can become followers, sponsorship leverage, affiliate clicks, live viewers, or payouts where TikTok’s programs apply. The exact payment differs by account and market, while the attention logic remains stable: a loaded query offers a cheap title and a prequalified audience.
Evidence costs time. Repetition is fast. A creator can place the suggested phrase on screen, restate several posts from other accounts, add a clip of unrelated body language, and promise an answer after enough throat-clearing to improve retention. Another creator responds.
Fan accounts clip the response. Searchers encounter a page full of videos and mistake quantity for corroboration, although several clips may trace back to the same unsupported post.
TikTok benefits even when nobody pays for the individual search. A disputed celebrity story creates more searches, longer result sessions, repeat visits, and fresh videos, all of which supply attention around which the wider advertising business operates. The platform’s interest is not necessarily belief. Continued inspection is enough.
This helps explain why the harmless framing fails. Autocomplete is useful for correcting spelling, finding a title, or reaching a known topic quickly. The same speed becomes dangerous when the completion targets health, sexuality, pregnancy, addiction, abuse, criminal conduct, or a person’s body. The interface collapses unequal claims into matching rows of text.
A credited cast list and an unsupported allegation can look equally searchable. They are not equally grounded.
An audit has to test amplification
Counting how often a rumor appears among suggestions is only the first pass. The stronger test asks what the interface adds.
Start with the shortest neutral stem that identifies the subject. Capture the ordered suggestions without tapping. Add one letter at a time and capture them again. Repeat the run with the factual control stories, then compare how quickly TikTok moves from identification to speculation.
A completion that appears only after most of an allegation has been typed mainly helps finish the user’s thought. One that appears after a neutral name or title teaches the thought to the user.
Ranking position matters too. The first completion is easier to tap and carries more visual authority than a phrase at the bottom. Persistence matters. A suggestion that survives across logged-out sessions, clean accounts, and repeated checks looks less like narrow personalization.
Result quality matters most: after recording the completion, reviewers should inspect whether the leading videos cite primary documents, recycle other TikToks, or provide no support at all.
This method cannot reveal TikTok’s private ranking formula. It can distinguish retrieval from amplification. That is the point.
The company could make different product choices without abolishing search. It could decline to autocomplete sensitive allegations about identifiable people unless the query concerns a well-documented public event. It could attach context to fast-rising phrases, explain that suggestions reflect activity rather than verified facts, and reduce the weight of taps generated by the suggestion itself. Otherwise the system grades its own homework.
TikTok could also give researchers a stable archive of suggestion changes by region and month, with privacy safeguards, so that outside auditors can identify when a false premise migrated from user posts into platform text. At present, the burden falls on reporters taking repeated screenshots before the menu changes again.
The final check returns to those two words. Type “Wicked cast.” Stop. Whatever appears next was not contained in the query.
TikTok put it there.
Questions people ask
Does
TikTok autocomplete prove that a rumor is popular?
No. A suggestion shows that TikTok ranked a phrase as a useful completion under particular conditions. It does not reveal how many people searched it, whether those searches were independent, whether the claim is true, or how much activity TikTok’s own earlier suggestions generated.
Can a clean TikTok account remove personalization?
It can reduce personalization from follows, likes, watch history, and earlier searches. It cannot remove every contextual signal, including language, broad location, device information, and platform-wide trends, so researchers should record those conditions and repeat the test rather than treating one screen as universal.
How does autocomplete help a celebrity rumor spread?
It places the rumor-shaped phrase in front of users who entered only a neutral name or title. Taps then create search traffic, creators make videos for that traffic, and the new supply can produce more curiosity, giving TikTok fresh behavioral signals that may reinforce the same completion.
What should TikTok change about search suggestions?
TikTok should stop completing sensitive personal allegations from neutral query stems unless the subject is tied to a well-documented public event. It should also label suggestions as activity-based rather than verified, prevent suggestion-generated taps from automatically strengthening the same phrase, and preserve auditable records of major changes.
One update a day
Today's story, in your inbox
One story each morning — no hype, no filler, no algorithm deciding for you.