The AI Reaction Face Never Had to Watch the Falling Mug
A caption, synthetic voice and avatar can turn recycled footage into commentary without anyone seeing the original. Platforms reward the measurable performance of reaction, not proof that one occurred.
August 26, 2026 · 7 min read
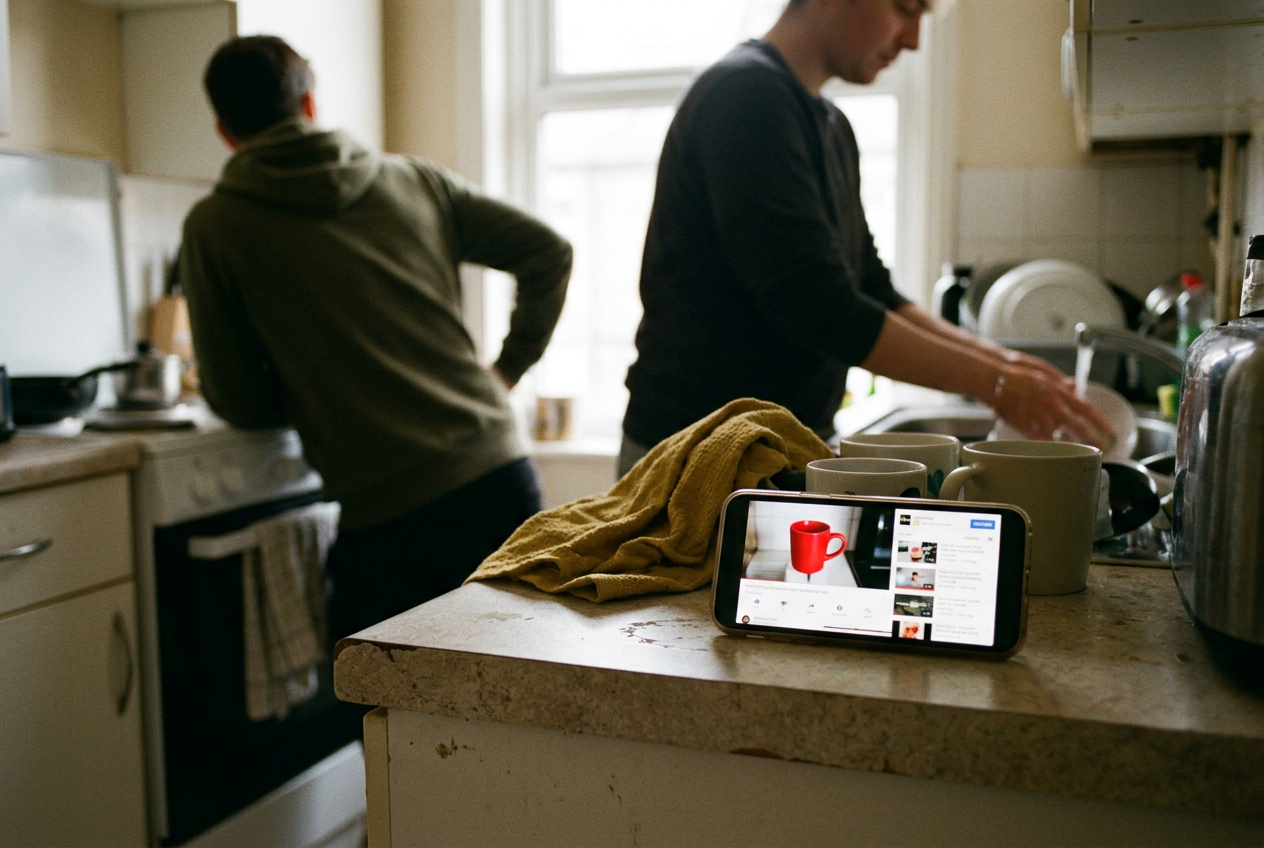
The clip lasted twelve seconds. A red ceramic mug slid across a kitchen counter, tipped near the edge and was caught by a hand before it hit the floor. A yellow dish towel in the background did not move. There was no dialogue, no reveal worth explaining and no emotional content beyond the small relief of avoiding broken crockery.
It was enough.
For a controlled test, I used the clip to build the kind of vertical reaction video that fills TikTok, Instagram Reels and YouTube Shorts: source footage taking up most of the frame, a synthetic presenter above it, large captions in the center and commentary that insists something important is about to happen. The presenter never received the video. The script generator got a still frame and a typed synopsis. The voice tool got only the script.
The avatar tool got only the audio.
The final presenter widened its eyes, moved its mouth and delivered a plausible reaction around the falling mug. It had no more access to the event than a microwave has to lunch.
That separation is the format’s real innovation. AI reaction video does not automate watching. It removes watching from the production line.
The reaction is assembled backward
A human reaction begins with perception. Someone watches a clip, forms a response, then speaks. Synthetic commentary can reverse that order because each component only needs enough information to imitate the next one.
The source layer can be any recycled video that already contains movement, suspense or a recognizable setup. The commentary layer begins as text, often generated from a caption, thumbnail, scraped description or a few sampled frames. A multimodal model, meaning a system that can process more than one kind of input, may inspect the whole video, but it does not have to. The cheapest workflow gives it a summary and asks for a hook, escalating remarks and a closing prompt.
Text-to-speech software then converts the script into narration. Services such as ElevenLabs offer generated voices, while avatar platforms such as HeyGen can animate a digital presenter to match an audio track. Lip sync, the automated matching of mouth movements to speech, supplies the visible evidence that a person is talking. CapCut or a similar editor can place that presenter over the original footage, generate captions and resize the package for several platforms.
None of these tools needs to understand the red mug as an event. Each performs a narrower job. The script needs to resemble commentary. The voice needs to resemble speech.
The face needs to move at approximately the right moments. The editor needs to keep something changing on screen.
In my test, the most revealing failure was not a broken render or garbled sentence. It was competence. The generated commentary knew the mug was moving toward the edge because I supplied that fact, then padded the observation with generic anticipation and relief. It sounded like a reaction while containing no evidence of one.
Remove the footage and the narration could sit over almost any near-miss involving a dropped phone, a wobbling plate or a package sliding off a car roof.
The template does not require insight. Specificity would make it less reusable.
Platforms grade the package they can see
Recommendation systems, the software that selects and orders posts for each viewer, have access to behavioral signals rather than interior states. They can record whether someone watched to the end, replayed a section, paused, shared or opened the comments. Automated systems can also classify visible faces, speech, captions and scene changes, although the exact weighting of those features is proprietary and changes over time.
They cannot establish that the presenter experienced surprise.
The point is not that every short-form platform has a secret switch marked FACE BONUS. It is that a face, a voice and persistent captions create machine-readable activity while also giving viewers several places to look, which can support the retention signals platforms publicly emphasize. The source clip carries the event. The presenter supplies social framing.
Captions keep the video legible without sound and restate the hook for anyone who arrived halfway through.
The falling mug now produces two timelines. One asks whether the cup reaches the floor. The other asks when the presenter will deliver the promised reaction. Even weak commentary can delay resolution, especially when the edit repeats the approach to the counter’s edge or withholds the catch until the final seconds.
Retention, meaning how long viewers remain with a post, does not distinguish fascination from irritation. A person waiting to confirm that the commentary adds nothing still generates watch time. Someone replaying the clip to inspect an awkward mouth movement still generates a replay. Comments accusing the presenter of being synthetic remain comments.
Platforms do have policies around reused or unoriginal material, and some require labels for realistic synthetic media. Enforcement varies, while a reaction layout gives recycled footage the appearance of transformation: new face, new voice, new captions, new crop. A system looking for duplicate pixels may detect the underlying clip, but every added layer complicates the comparison and gives the uploader another export to test.
The reaction survives because authenticity is expensive to verify and engagement is already in the database.
The template turns one clip into inventory
The red mug required more time to film than to repurpose. Once the layout existed, I could replace the script, swap the voice or move the avatar without touching the source footage. Free tool tiers added watermarks and export limits, making high-volume production awkward, but paid access mainly buys throughput: more generations, faster rendering and fewer visible restrictions.
That changes the useful unit of production. A conventional creator spends attention on a video and hopes it performs. A synthetic-content operator can treat the same mug clip as inventory, producing variants with different hooks, caption positions and presenter styles, then keeping whichever export earns the strongest early response.
This is where the economics stop resembling criticism or performance and start resembling ad testing. Generation lowers the cost of each additional version, while platforms distribute posts to small initial audiences and expand reach when the response looks promising. A producer does not need every upload to work. Volume spreads the bet.
Payment may come from platform revenue programs where eligible, but the larger incentive can sit elsewhere: affiliate links, account growth, traffic sent to another page or an audience later redirected toward a product. The source creator may receive nothing, particularly when footage is stripped of attribution or copied through several intermediary accounts. Meanwhile, voice performers and recognizable creators face a separate risk when cloning tools imitate identities rather than generating an obviously fictional host.
The mug itself has no commercial value. The repeatable wrapper does.
Synthetic commentary is built to evade judgment
A bad human reaction can be judged against the person’s apparent response. They missed the point. They talked over the important moment. They exaggerated.
Synthetic commentary weakens that standard because there may be no original encounter to evaluate, only an output optimized to resemble the shape of one.
This matters beyond annoyance. Reaction has long functioned as a loose claim of transformation, a way to frame copied material as commentary rather than straight reposting. Copyright questions still depend on context and jurisdiction, and a face in the corner does not automatically make reuse lawful. Yet platform interfaces reduce that dispute to visible ingredients.
Commentary appears to be present. The upload moves forward. Any rights complaint arrives later, if it arrives at all.
The obvious platform response is better detection, but detection alone creates another generation contest. Producers can vary crops, timing, overlays and voices faster than a moderation team can review context. Synthetic-media labels may tell viewers how a presenter was made, though they do not answer whether the underlying footage was licensed or whether the commentary contains any meaningful engagement with it.
A stronger originality standard would examine contribution rather than decoration. Platforms already compare media for rights management and duplicate detection. They could reduce distribution or monetization when recycled footage supplies nearly all the informational value and the added layer consists of interchangeable narration. That would still require appeals, especially for criticism, remix and accessibility work where reused material has a legitimate purpose.
The test should not be whether a face moves. It should be whether the upload gives the viewer something that was not already sitting inside the source.
My synthetic presenter failed that test. It reacted fluently to the red mug, never noticed the unmoving yellow towel and could not have known whether the hand caught anything. The system did not malfunction. It delivered the exact commodity the template requested: measurable signs of attention with no attention behind them.
Questions people ask
What tools are used to make AI reaction videos?
A typical workflow combines a script generator, text-to-speech software, an avatar or lip-sync service and a vertical-video editor such as CapCut. The tools can receive separate inputs, so the avatar never needs the source clip. One operator can build the commentary from a caption, a thumbnail or a short description.
Do
TikTok, Instagram and YouTube reward AI faces?
There is no public evidence of a universal ranking bonus for synthetic faces. Platforms do measure watch time, completion, replays and interaction, while automated systems can identify audiovisual features. Reaction templates package recycled footage in ways that can produce those measurable behaviors, even when the commentary is generic or irritating.
Is an
AI reaction video deceptive if it is labeled?
A synthetic-media label can disclose that the presenter was generated, but it does not show whether the system watched the footage, whether the uploader licensed it or whether the commentary adds anything. Labeling answers how the face was made. It does not settle what the reaction claims to represent.
How could platforms reduce synthetic reaction spam?
They could make originality matter more for recommendation and monetization, examine whether added commentary contributes information, and give source creators workable attribution and appeal tools. Duplicate detection alone will miss altered exports. The useful comparison is between the value supplied by the recycled clip and the value supplied by the face above the mug.
One update a day
Today's story, in your inbox
One story each morning — no hype, no filler, no algorithm deciding for you.