Why AI Voiceovers Keep Calling Reading “REE-ding”
Recurring AI pronunciation errors are more than bad narration. They can expose shared text-to-speech tools, copied scripts and the assembly lines behind supposedly independent channels.
August 28, 2026 · 7 min read
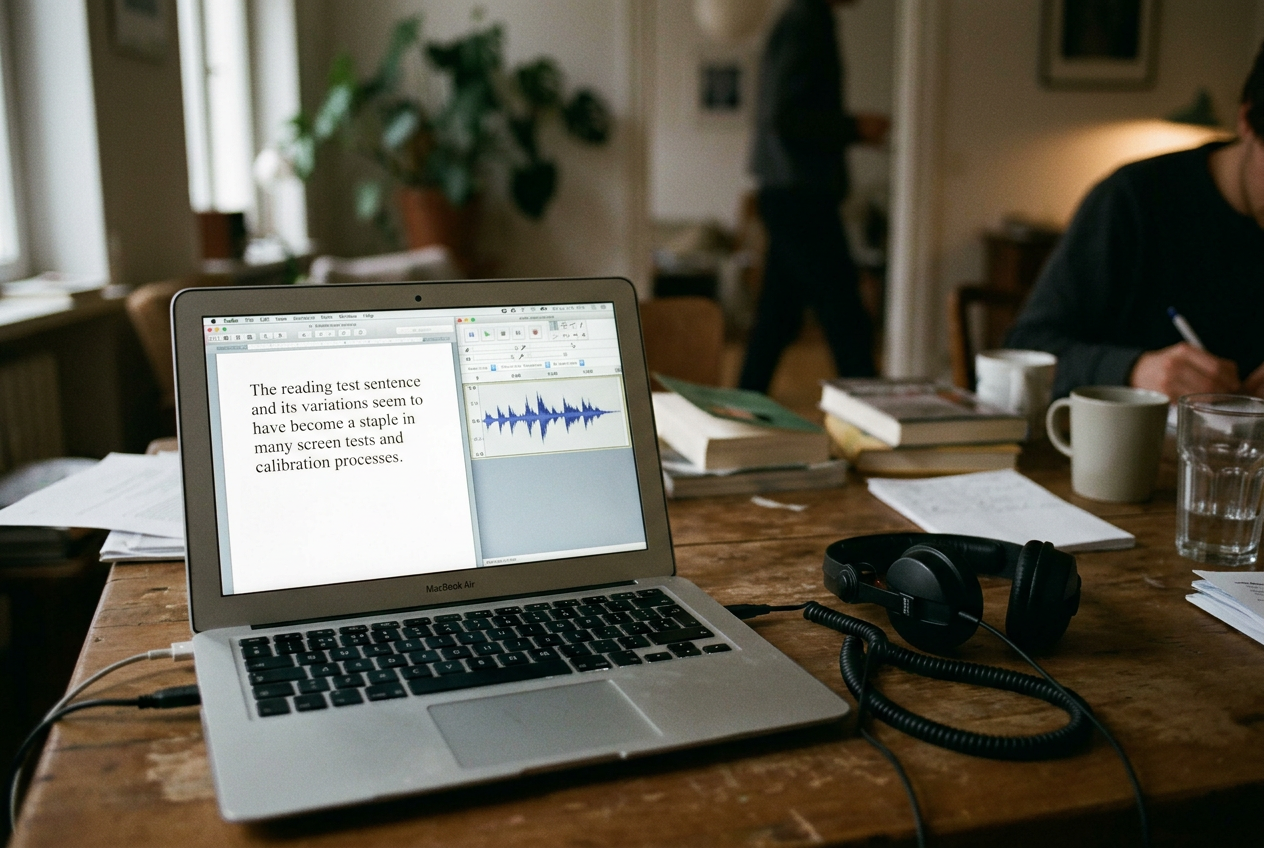
The test sentence was ordinary enough to pass through a content mill without waking anybody up: “Officials in Reading, Pennsylvania, said the lead pipes were replaced.”
It contains two traps. Reading, the city, is pronounced “REDD-ing,” while lead, the metal, is pronounced “led.” Feed the sentence into a consumer text-to-speech tool, which converts written language into synthetic speech, and either word can expose what happened between script and upload. Reading may become “REE-ding.
” Lead may become “leed.” The voice remains serenely confident. It has never had to ask for directions in Pennsylvania.
For this evaluation, I ran the line through consumer-facing text-to-speech interfaces, replayed each export and then changed only the text around the disputed words. The outputs varied between voices, which is important, but a voice that chose the wrong pronunciation usually repeated that choice when given the same wording again. Adding “Pennsylvania” did not always rescue Reading. Rewriting the city as “Redding” did.
That stability is what makes the mistake useful. When several unrelated vertical-video accounts pronounce an unusual place name incorrectly in the same way, with the same pause before it or the same stress afterward, you may be hearing more than generalized machine incompetence. You may be hearing a production fingerprint.
The error enters before the voice speaks
A text-to-speech system does not look at a word and retrieve one eternal correct sound. It cleans the text, divides it into manageable units and predicts pronunciation from spelling plus context. Text normalization, the stage that converts forms such as abbreviations and numerals into speakable words, can alter the sentence before the voice model receives it. A later component maps letters to likely sounds.
This works well for language that behaves itself. English declined the invitation.
Reading can be an activity, a place in Pennsylvania or a town in England, and those meanings do not share one pronunciation. Lead can be a verb or a metal. Names are worse because local usage often defeats the most statistically common reading, while scraped training material may contain the spelling many times without enough reliable audio attached to it.
Punctuation matters too. A comma can change the pause around a word, which changes how some systems interpret the surrounding phrase. Capitalization may help one voice and do nothing for another. Replacing Reading with “Redding” is crude but effective because it removes the ambiguity, although it creates a fresh problem if the narration text also becomes the on-screen caption.
The city is now pronounced correctly and spelled incorrectly. Efficiency has taken another hostage.
More advanced tools may accept a pronunciation dictionary or Speech Synthesis Markup Language, usually called SSML, which lets a producer specify pauses, emphasis or phonetic pronunciation. Many fast-turnaround channels never touch those controls. They paste a script, select a voice and export. The default interpretation becomes the final performance.
The Reading error therefore says something precise. The producer either did not listen through, noticed and accepted it, or lacked an easy way to repair the word without disrupting captions and timing. None of those explanations involves a robot spontaneously developing an accent.
One mistake can travel through several factories
The simplest route is a repost. An account downloads a finished video or lifts its audio, changes the crop, adds a border and uploads it again. Reading stays “REE-ding” because the mistake is baked into the waveform. The voice, pause and surrounding breaths or artifacts remain identical, even if the captions have been restyled in urgent yellow.
The next route is copied source text. Content channels routinely work from the same article, public post, transcript or generated summary, whether through direct copying or through tools that preserve much of the original sentence structure. If several operators paste “Officials in Reading, Pennsylvania” into the same speech engine, the same ambiguity reaches the same pronunciation system. Different background footage does not make the production independent.
Copycat channels can also share a template without sharing files. A common assembly line starts with a trending subject, turns available text into a short script, renders narration, attaches stock footage or borrowed clips, generates captions and uploads. A person may supervise every stage, but speed sets the standard. The economic advantage comes from reducing attention per video, so listening closely to a place name cuts against the workflow’s main purpose.
This is why the fingerprint has levels. Identical audio under different visuals strongly suggests reused narration or a repost. Matching errors with matching pauses may indicate the same render or a shared voice configuration. The same wrong vowel delivered with different timing is weaker evidence, because separate tools can make the same obvious mistake.
A pronunciation error is not DNA. It cannot identify an exact account owner, prove coordination or tell you which subscription plan somebody bought. It can narrow the workflow, especially when it appears alongside the same caption breaks, repeated script phrasing and identical ordering of facts. The clue becomes persuasive through combination, not confidence.
Reading is especially useful because a human familiar with the place is unlikely to choose “REE-ding,” while a system resolving the word from common written context has an understandable reason to do so. The error points back toward text handling. That is much more informative than deciding the narrator merely sounds fake.
Voice choice disguises shared machinery
Synthetic voices are sold as variety. Change the gender presentation, speaking speed or emotional preset and the output feels like a new host, at least until every host trips over the same noun.
The audible voice is only the surface layer. Multiple voices inside one product can share text normalization rules, pronunciation dictionaries or upstream language models, so their tone changes while their lexical blind spots remain. Separate products may also rely on related underlying services, though pronunciation alone cannot establish that relationship.
This matters on feeds because apparent abundance is part of the pitch. Ten accounts cover the same celebrity clip, strange court filing or local disaster, each with a different avatar and narrator, and the repetition looks like broad interest rather than duplicated production. The platform shows posts, not supply chains. It rarely tells a viewer whether the narration was generated from copied text, purchased as a template or recycled from another upload.
Recommendation systems, which rank content by predicted viewer response, have little reason to punish a wrong vowel unless viewers leave. Their internal signals and weightings are not fully public, but the basic incentive is visible: a pronunciation error that survives long enough to deliver the hook can still earn distribution. Corrections in the comments may even extend attention around the post, although that does not mean the platform deliberately rewards bad pronunciation.
The people who benefit are the operators who can publish more material with less listening, along with tool vendors paid for generation or editing. Platforms receive inventory that keeps the feed moving. Viewers pay in attention, and the person or place being described absorbs the distortion.
For harmless trivia, that may amount to a mangled town name. In reporting about health, crime or public safety, the same workflow can misread medication names, confuse people with similar surnames or detach a warning from the place it concerns. Synthetic certainty makes the failure worse. The voice does not hesitate when the script is ambiguous.
It commits.
The fix costs the thing slop removes
The reliable correction is human review. Listen to the export with the script open, isolate names and ambiguous words, then use a pronunciation field where the tool provides one. If it does not, change the narration copy while keeping a correctly spelled caption track separate.
That requires another playback pass and a small amount of editorial judgment. At scale, those costs accumulate, which is exactly why low-attention production sheds them. The same economics that make synthetic narration attractive also preserve its most revealing mistakes.
The Reading test exposes the trade. “Redding” can repair the sound quickly, but someone must notice the problem, maintain separate display text and re-export the clip. A channel built to chase whatever is moving through the feed may prefer the wrong city delivered on time.
That makes recurring errors worth hearing closely. They show where the producer stopped checking, where a template took over and where several nominally separate accounts may share one hidden layer of machinery.
Questions people ask
Why do different AI voices mispronounce the same word?
Different voices can share pronunciation rules, dictionaries or the same underlying text-processing system. They may sound unlike one another while resolving an ambiguous spelling identically. Separate channels can also feed copied scripts into the same tool, reproducing the mistake without sharing a finished audio file.
Can a mispronunciation identify the exact text-to-speech app?
Usually not by itself. Common homographs and place names can defeat several systems in similar ways. An exact voice, matching pauses, identical caption breaks and the same unusual error create a stronger fingerprint, but they still support a production inference rather than definitive attribution.
Why do correct captions appear under incorrect narration?
Captioning and narration may come from separate stages. A producer can preserve the original spelling on screen while using a phonetic rewrite for speech, or an automatic caption system can recover the intended word from context after the voice says it badly. Correct text does not prove a human checked the audio.
How can creators stop AI voiceovers from mispronouncing names?
Use a pronunciation dictionary or phonetic controls when available, and keep narration text separate from display captions if a spelling workaround is necessary. The essential step is still a full playback before upload. Someone has to hear “Reading, Pennsylvania” and reject “REE-ding.”
One update a day
Today's story, in your inbox
One story each morning — no hype, no filler, no algorithm deciding for you.